Learn how synthetic data accelerates AI training while protecting privacy, reducing data risks, and helping businesses build reliable machine learning models.
AI models are only as good as the data you feed them. But here’s the problem: getting high-quality, real-world data is harder than it sounds. It’s expensive. It’s slow. And in regulated industries, it comes with compliance risks that can stall an entire project before it leaves the ground.
That’s exactly why more enterprises are turning to synthetic data generation as a smarter path forward. It solves the data scarcity problem without putting real people’s information at risk.
Let’s break down what this actually means for your AI strategy.
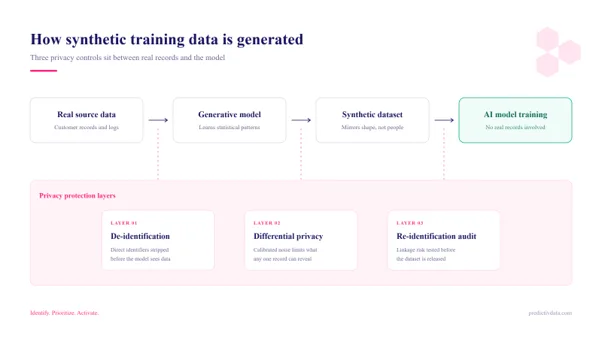
Synthetic data generation is the process of creating artificial datasets that statistically mirror real-world data, without containing any actual personal or sensitive information. Think of it as a simulation layer for AI training data.
Instead of pulling from live customer records, medical files, or financial transactions, teams use AI data generation software and statistical models to produce data that behaves like the real thing. The distributions match. The correlations hold. But there’s no identifiable individual behind any of it.
This is not a workaround or a shortcut. It’s a legitimate, increasingly mainstream method being adopted by enterprises that need to move fast without compromising on compliance.
Most AI teams already know the pain points, but they’re worth naming:
Data scarcity is the most obvious one. Edge cases are rare by definition, so your training sets may never capture enough of them to build a robust model. A fraud detection system trained on limited fraud examples, for instance, will struggle in production.
Data privacy in AI is the other major concern. GDPR, HIPAA, CCPA and a growing list of regional frameworks put strict limits on how personal data can be used. Even with anonymization, re-identification risks remain. A single compliance failure can translate to significant financial and reputational damage.
There’s also the time factor. Collecting, cleaning, and labeling real-world data takes months. That’s months your competitors aren’t waiting.
This is where synthetic data generation tools earn their place in the enterprise stack.
A few industries are ahead of the curve here.
These aren’t pilots or proofs of concept anymore. They’re production-grade applications of privacy-preserving AI at scale.
Not all approaches are equal. When evaluating synthetic data generation tools or vendors, a few capabilities matter most:
Synthetic data for machine learning is powerful, but it’s not without nuance. If the generative model itself is trained on flawed or biased real data, those biases can be replicated and even amplified in the synthetic output. This is sometimes called mode collapse or distributional shift.
The takeaway isn’t that synthetic data is risky. It’s that the quality of your input, and the rigor of your validation process, determines the quality of your output. That’s true of any data strategy.
Done well, synthetic data generation gives you scale, speed, and compliance without the trade-offs you’d normally have to accept.
Organizations that are serious about AI at scale are moving toward architectures where privacy-preserving AI isn’t an afterthought. It’s a design principle.
Synthetic data is one pillar of that architecture. Federated learning, differential privacy, and robust data governance are others. Together, they make it possible to build capable, high-performing AI systems while meeting the expectations of regulators, customers, and boards.
The enterprises that figure this out early will have a meaningful advantage. Not because they moved fastest, but because they built on a foundation that holds up under scrutiny.
Synthetic data in AI refers to artificially generated datasets that replicate the statistical properties of real data without containing any actual personal or sensitive information. It’s used to train, test, and validate AI and machine learning models.
It’s generated using methods like generative adversarial networks (GANs), variational autoencoders (VAEs), rule-based simulations, and statistical modeling. These approaches learn the structure and patterns of real data and produce new records that behave similarly.
It addresses common bottlenecks in AI development by providing scalable, on-demand datasets, filling gaps in rare or underrepresented scenarios, and enabling faster iteration without waiting on data collection or approval cycles.
Not categorically, but it’s often more practical. Synthetic data is faster to produce, easier to share, and carries fewer compliance risks. In many workflows, it’s used alongside real data through augmentation rather than as a full replacement.
Because it contains no real personal information, synthetic data eliminates the risk of re-identification and falls outside the scope of most data privacy regulations. This makes it safe to share across teams, geographies, and third-party vendors without triggering compliance concerns.